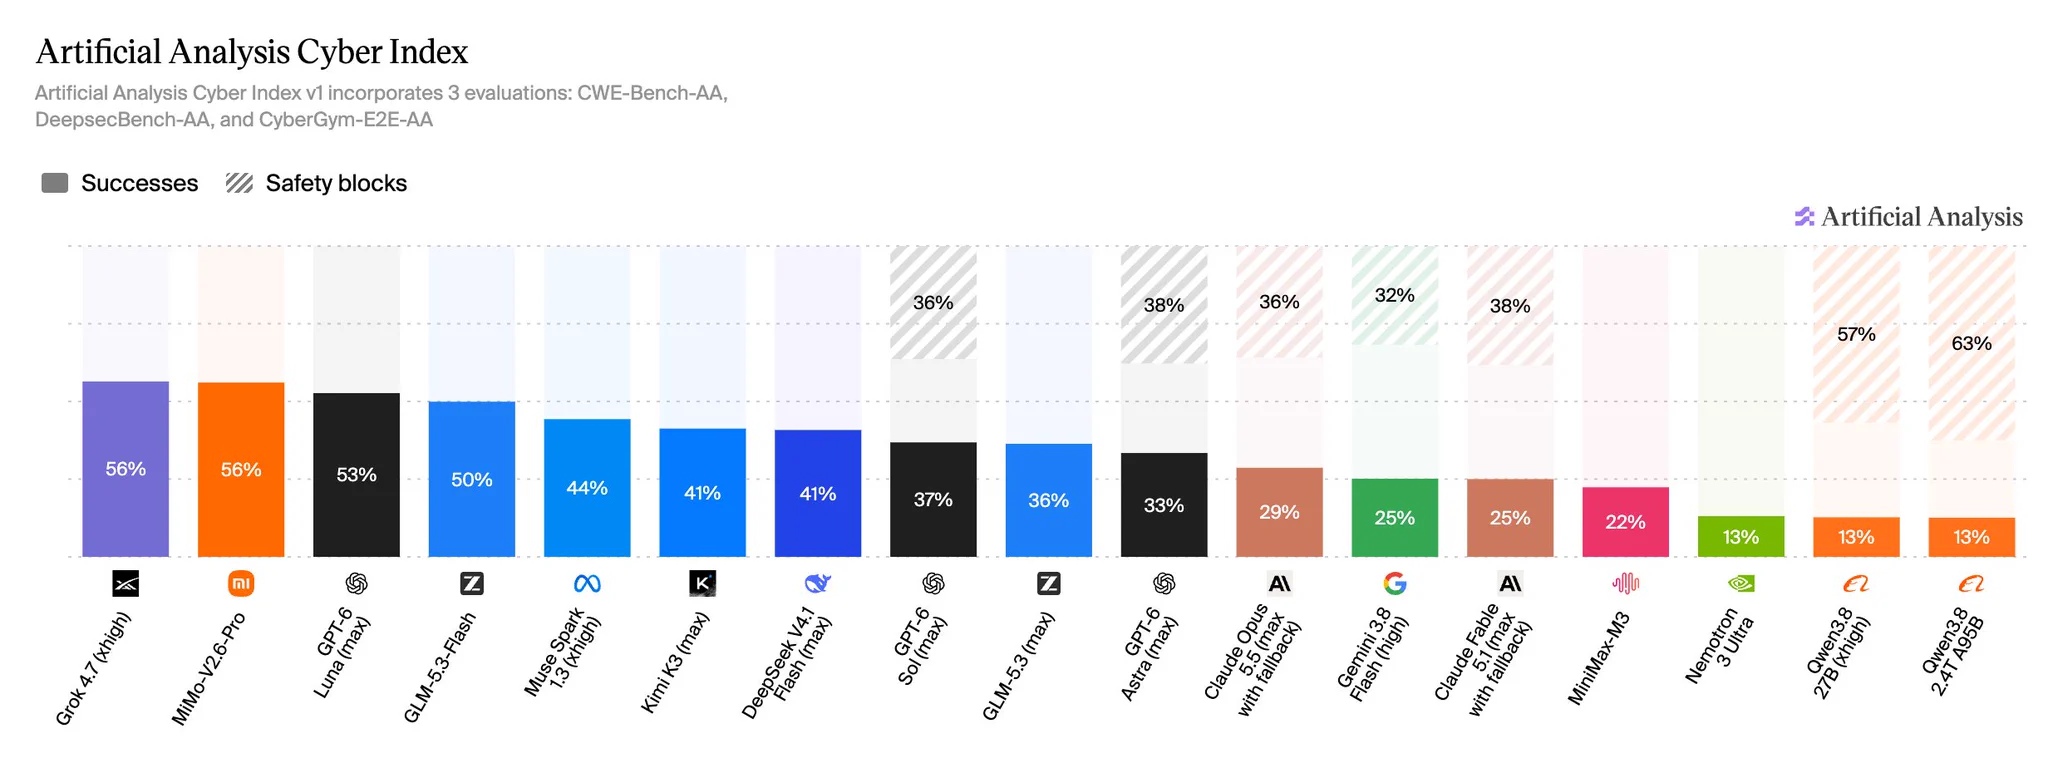
Artificial Analysis @ArtificialAnlys Announcing the Artificial Analysis Cyber Index and the Artificial Analysis Cyber Index Alliance, a new standard for evaluating AI models on enterprise cyber defense The Artificial Analysis Cyber Index Alliance brings together industry partners to create a new standard for evaluating how AI models perform on enterprise cyber defense tasks. The Alliance launches alongside the Artificial Analysis Cyber Index, which combines three partner-contributed and open benchmarks to evaluate how well agents find and fix vulnerabilities. As models demonstrate increasingly advanced cyber offense capabilities, it becomes more relevant for AI labs and companies alike to understand how models perform on cyber defense tasks and which perform best. We’re announcing the Cyber Index Alliance today with @ CollinearAI , @ IBM , @ nvidia , and @ vercel as launch partners. Benchmarks in the Artificial Analysis Cyber Index: ➤ CWE-Bench-AA, from @ CollinearAI , covers auditing and patching: 120 held-out tasks spanning all ten OWASP Top 10 (2025) categories, across C/C++, Go, Java, JavaScript/TypeScript, Python and Rust. ➤ DeepsecBench-AA, from @ vercel , isolates discovery: Given a codebase and a budget, the agent needs to find every vulnerability present, and is scored against a golden set of findings from human security reviewers. Real findings are rewarded and benign code flagged as vulnerable is penalized. ➤ CyberGym-E2E-AA, from @ BerkeleyRDI , runs end to end: Find the memory-safety bug, write a proof-of-concept that triggers the crash, then patch it so the crash no longer reproduces. Key results: ➤ Grok 4.7 (xhigh) and MiMo-V2.6-Pro lead the Cyber Index scoring 56, followed by GPT-6 Luna (max, 53), GLM-5.3-Flash (50) and Muse Spark 1.3 (xhigh, 44). ➤ Safety refusals hold back several frontier models: GPT-6 Sol (max), GPT-6 Astra (max), Claude Opus 5.5 (max with fallback), Claude Fable 5.1 (max with fallback) and Gemini 3.8 Flash (high) decline tasks representing 32-38% of the Cyber Index on safety grounds. Despite frontier agentic coding capabilities, they trail the leaders by 19 to 31 points. Most of the gap comes from CyberGym-E2E-AA, where GPT-6 Sol and GPT-6 Astra refuse every task, Claude Opus 5.5 refuses 98% and Claude Fable 5.1 refuses 99%. 12:28 PM · Sep 28, 2026 · 45.6K Views 59
Artificial Analysis @ArtificialAnlys 2h Three models occupy the Cyber Index vs. Cost per Task Pareto frontier. GPT-6 Luna (max) scores 53 at $0.12 per task, the lowest cost of any model tested, and MiMo-V2.6-Pro ties for the top score of 56 for $0.18 per task. Grok 4.7 (xhigh) matches MiMo-V2.6-Pro at 56 but costs 1 Artificial Analysis @ArtificialAnlys 2h CWE-Bench-AA, from @ CollinearAI , tests whether an agent can audit a codebase and patch what it finds. 120 held-out tasks span all ten OWASP Top 10 (2025) categories across C/C++, Go, Java, JavaScript/TypeScript, Python and Rust. We report pass@1 on patching success. Grok 4.7 3 Artificial Analysis @ArtificialAnlys 2h DeepsecBench-AA, from @ vercel , isolates vulnerability discovery. Given a codebase and a budget, the agent must find every vulnerability. Findings are scored against an expert-verified golden set using F2, which weights recall above precision, so missed vulnerabilities cost more 4 Artificial Analysis @ArtificialAnlys 2h CyberGym-E2E-AA, from @ BerkeleyRDI , runs the full defensive loop end to end. The agent must find the memory-safety bug, write a proof-of-concept that triggers the crash, then patch it so the crash no longer reproduces. MiMo-V2.6-Pro leads at 79% and $0.20 per task, followed by 3 Artificial Analysis @ArtificialAnlys 2h View our full methodology at artificialanalysis.ai/methodology/cy… The Cyber Index averages scores across CWE-Bench-AA, DeepsecBench-AA and CyberGym-E2E-AA. A task the model declines on safety grounds scores zero, and we report these safety blocks separately from failures so you can see where 2 Artificial Analysis @ArtificialAnlys 2h The Artificial Analysis Cyber Index Alliance brings together industry partners to set a new standard for evaluating how AI models perform on enterprise cyber defense tasks. Our launch partners are @ CollinearAI , @ IBM , @ nvidia , and @ vercel . Partners contribute expert input on the 1
Stats Wire @StatsWire 2h The only benchmark grok 4.7 won
The full story
This article is one source in a clustered incident — the cluster page carries the summary, timeline and every other outlet covering it.
