Build with the API / Brand and domain dark-web monitor
Brand and domain dark-web monitor
Are my brands or domains showing up on the dark web?
What you get
Matches a list of keywords (brand names, domains, subsidiaries) against ransomware leak-site victims and ransomware groups in one call, and prints the hits per bucket with dates and links.
- Endpoints
/darkweb/keyword-hits- Credits per run
- 3
- Key
- Works on the free key
Step by step
1. Get a key
Sign in, open Settings, then API & Feeds, and select Generate API key. The key is shown once, so copy it. Every account has one and the free key covers this recipe.
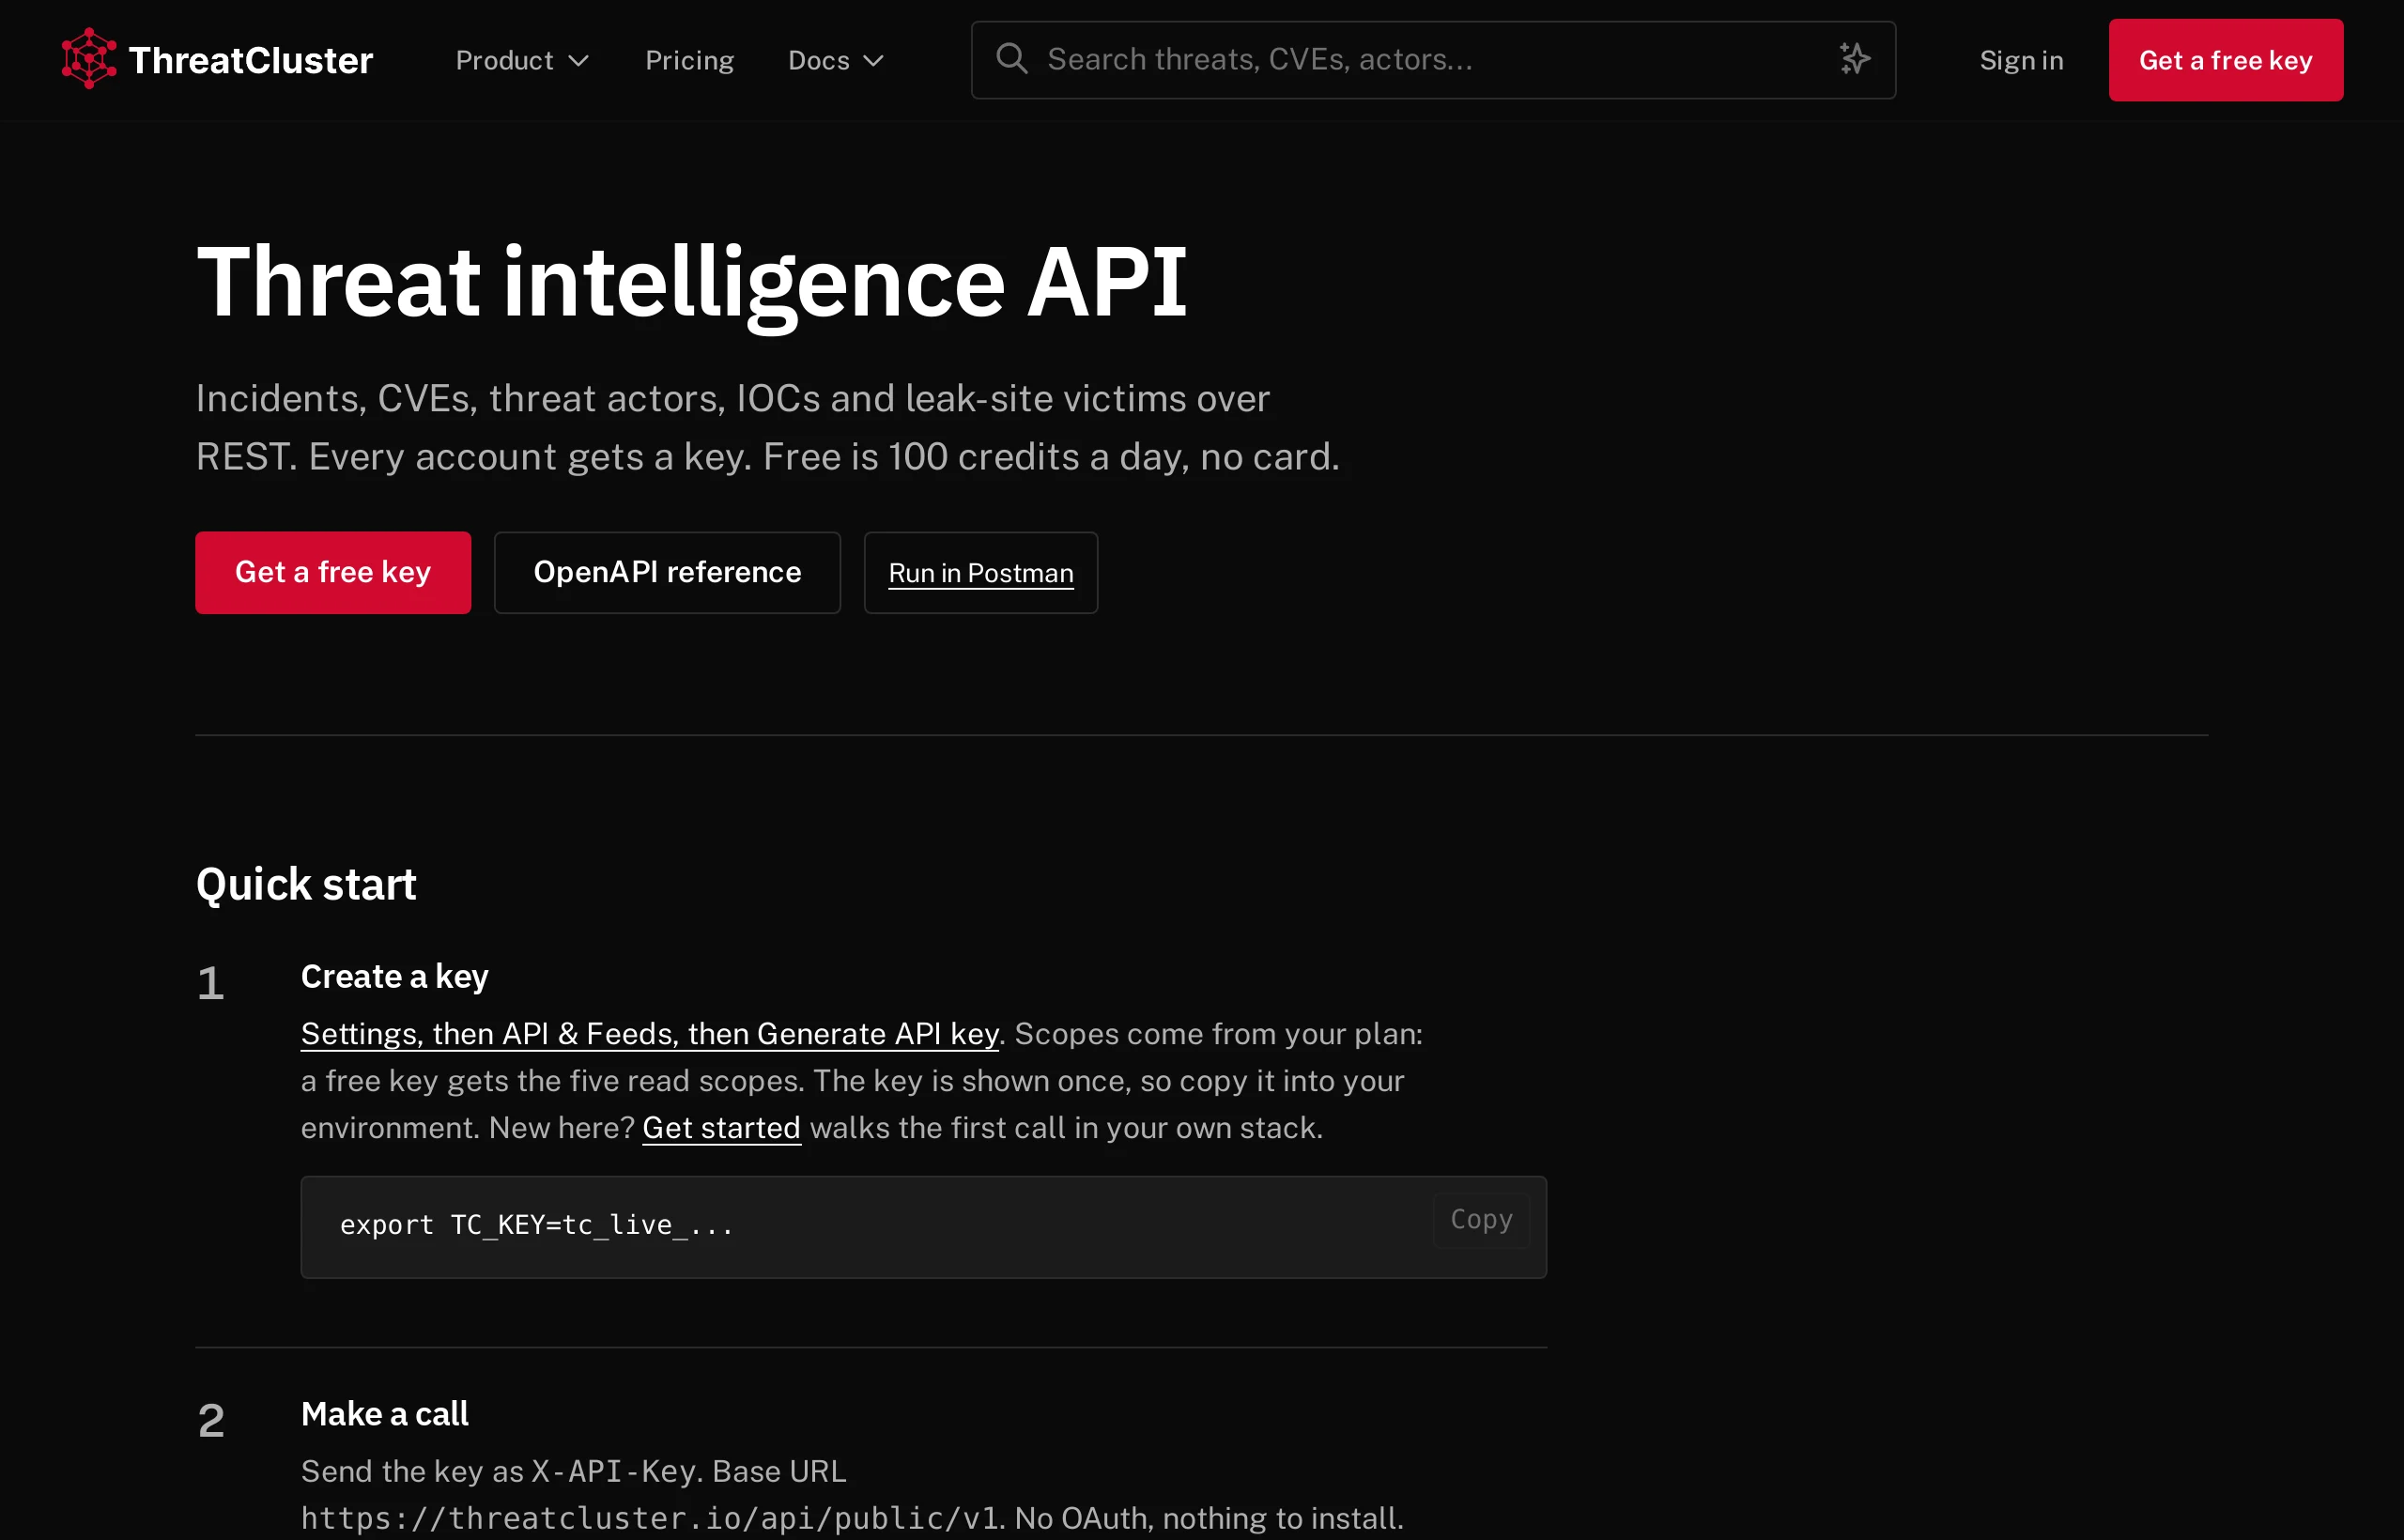
The API page. The key itself is created in Settings, under API & Feeds. 2. Download the script and set the key
The script is one file with one dependency. It reads the key from the environment, so the key never goes into the file.
curl -sO https://raw.githubusercontent.com/Jam0k/Cyber-Threat-Intelligence-API/main/examples/recipes/brand-domain-monitor.py
pip install requests
export THREATCLUSTER_API_KEY=tc_live_your_key_here
3. Run it
Run without arguments, the script searches for three generic words so there is something to see. It looks across leak-site listings, ransomware groups and incidents.
python3 brand-domain-monitor.py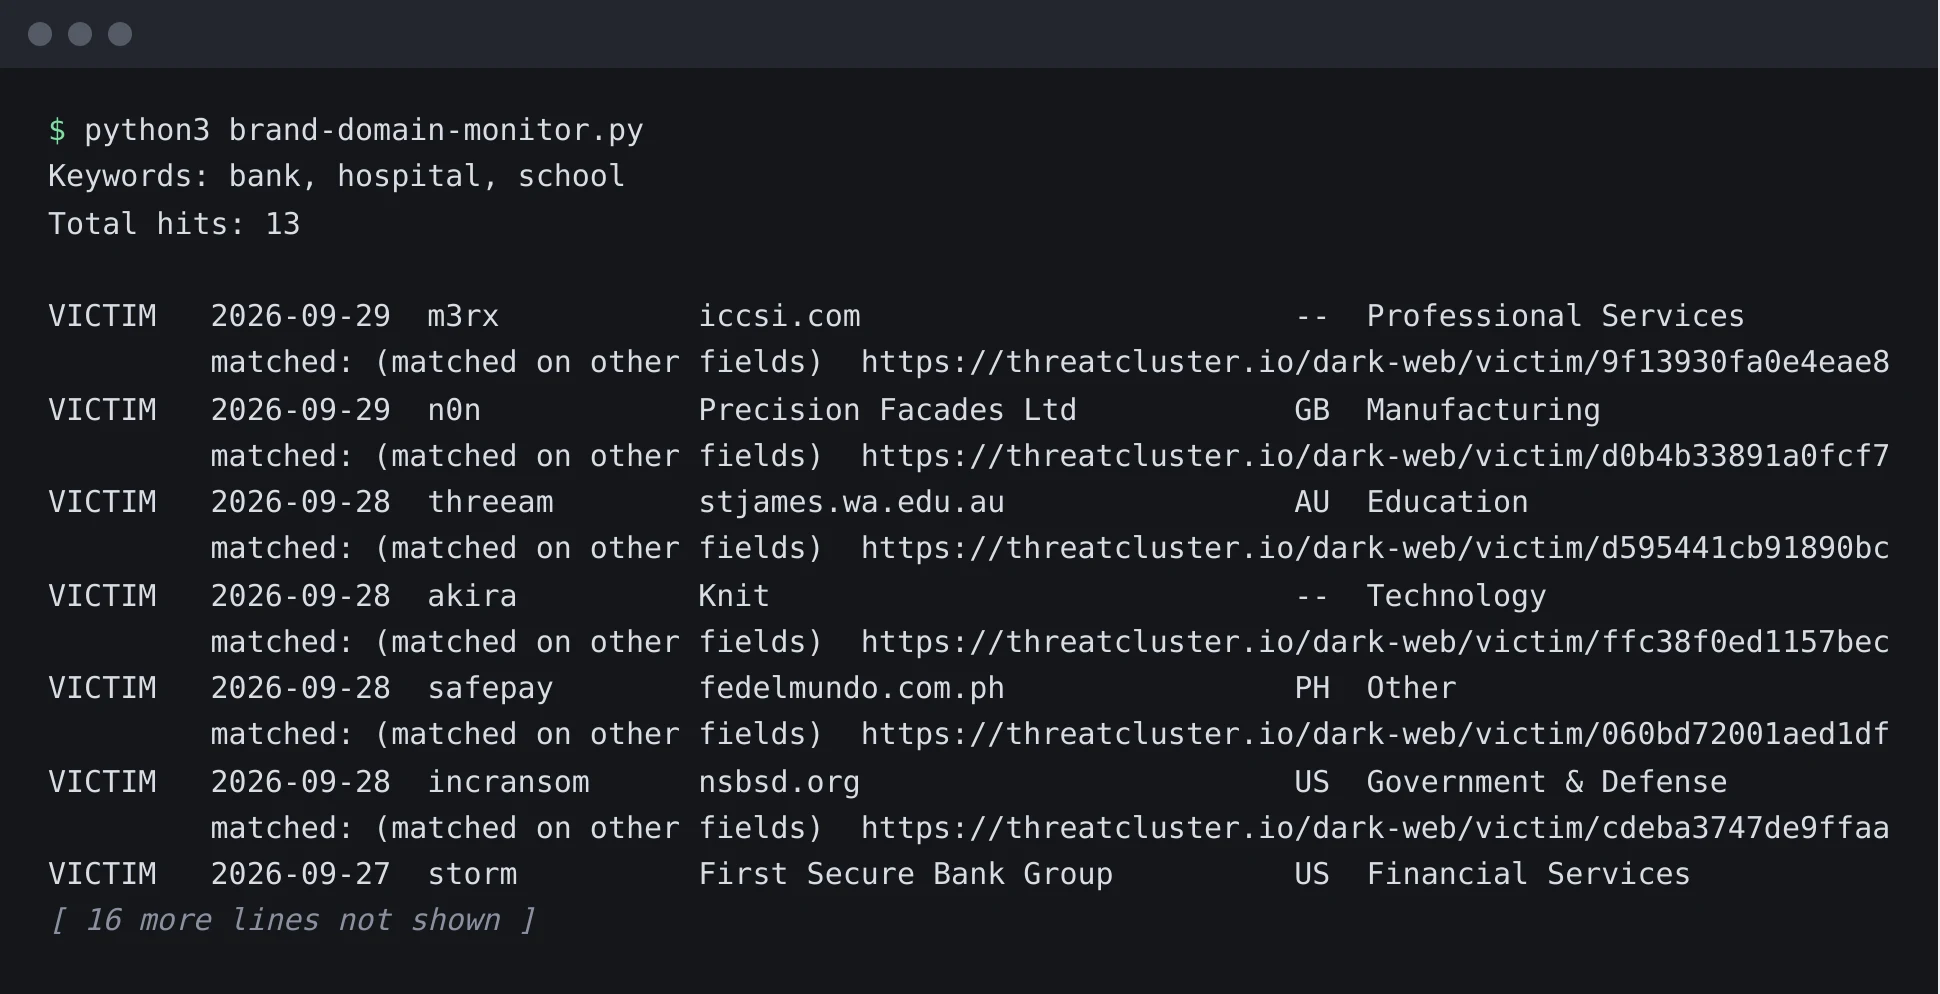
Run on 29 September 2026. 13 hits for the three default words. A listing is the group's claim, not a confirmed breach. 4. See the wider picture
The dark web page shows every tracked group and listing, by country, sector and time.
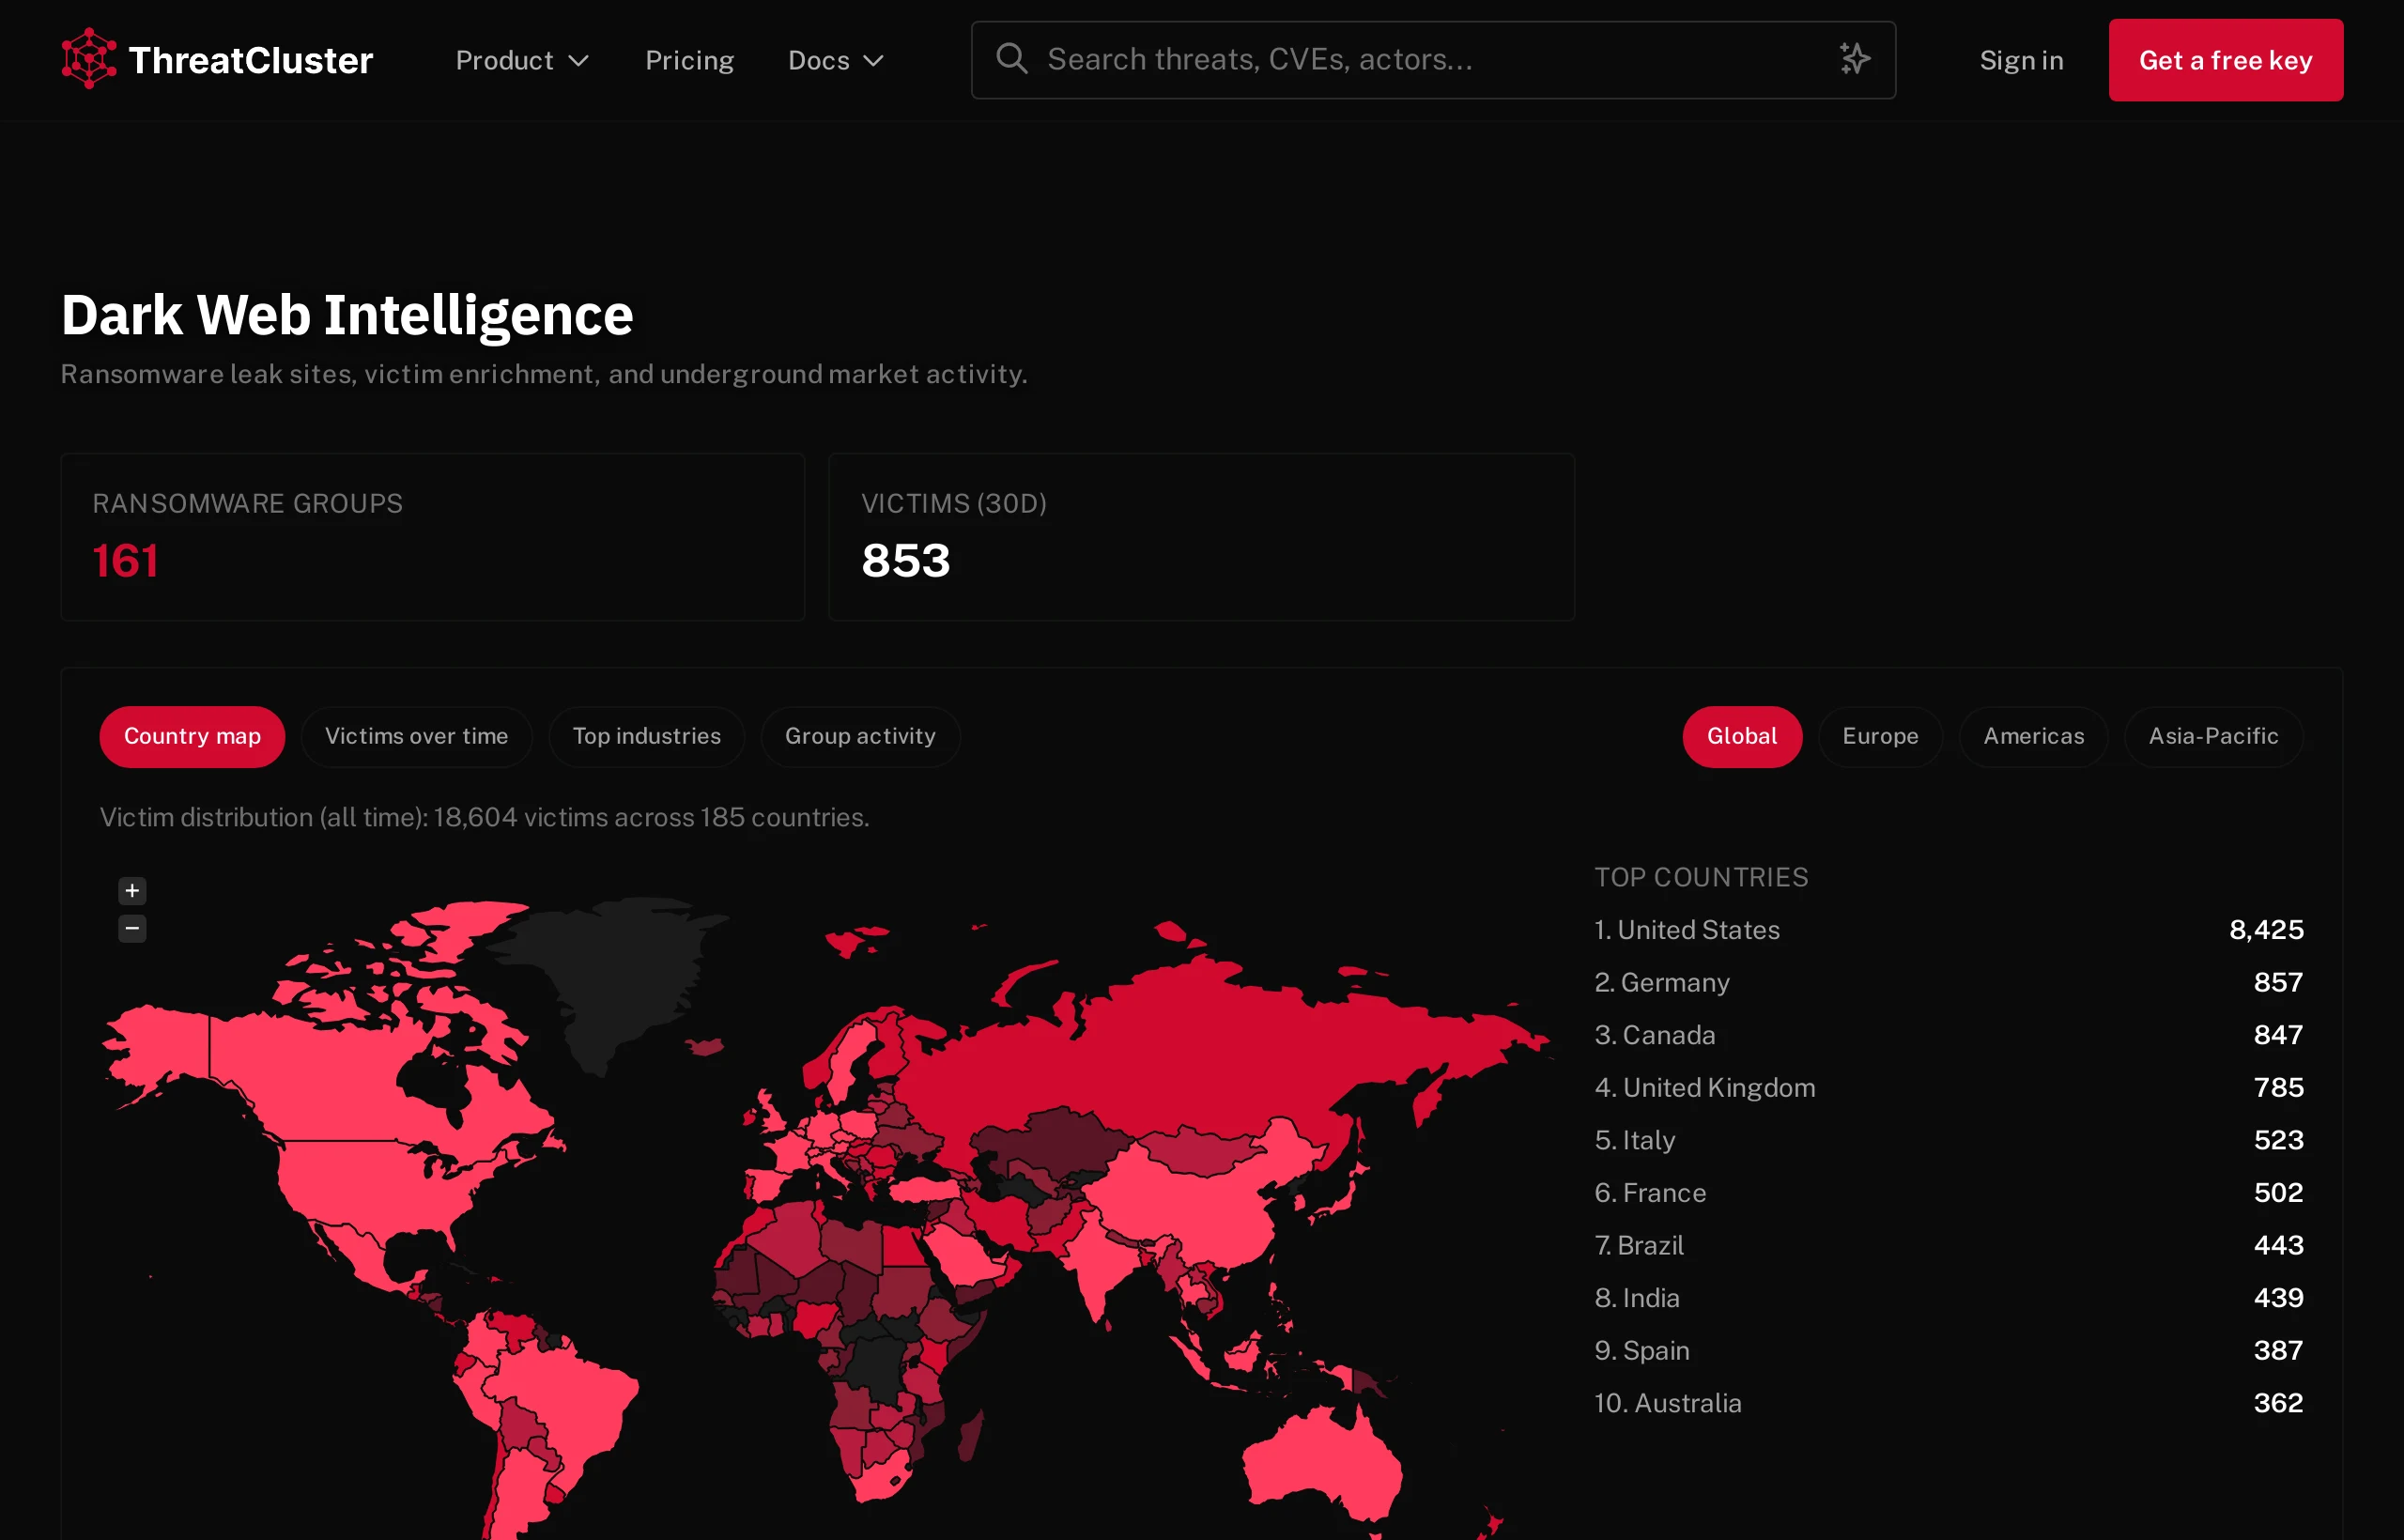
The tracker the hits above come from. 5. Watch your own names
Pass your brand names, your domains and your subsidiaries. No output means no match. The run costs 3 credits.
python3 brand-domain-monitor.py acme acme-corp.example "Acme Holdings"
The code
brand-domain-monitor.py, 106 lines. Python 3, needs requests.
#!/usr/bin/env python3
"""brand-domain-monitor: are my brands or domains showing up on the dark web?

What it does
  Matches a list of keywords (brand names, domains, subsidiaries) against ransomware
  leak-site victims and ransomware groups in one call,
  and prints the hits per bucket with dates and links.

Endpoints
  GET /darkweb/keyword-hits?keywords=a,b,c   (3 credits, however many keywords)

Cost: 3 credits per run. Works on the free tier (7-day window, up to 5 hits per bucket).

Usage
  python3 brand-domain-monitor.py acme acme-corp.example "Acme Holdings"
  (The default keywords are generic sector words, so the demo has something to show.)
"""
import argparse
import json
import os
import sys
import time

import requests

API_BASE = os.environ.get("THREATCLUSTER_API_BASE", "https://threatcluster.io/api/public/v1").rstrip("/")
API_KEY = os.environ.get("THREATCLUSTER_API_KEY", "")
SITE = os.environ.get("THREATCLUSTER_SITE", "https://threatcluster.io")  # where the linked pages live
PACE_SECONDS = 2.1  # free keys get 30 requests/min; ~28/min keeps loops clear of 429s
_credits = {"used": 0, "remaining": None}


def _auth_headers():
    # A tc_... key is sent as X-API-Key; anything else is a short-lived bearer (e.g. from `tc login`).
    if not API_KEY:
        sys.exit("THREATCLUSTER_API_KEY is not set. Free keys: https://threatcluster.io/about/api")
    if API_KEY.startswith("tc_"):
        return {"X-API-Key": API_KEY}
    return {"Authorization": "Bearer " + API_KEY}


def api_get(path, _allow=(), **params):
    """GET one endpoint. Exits non-zero with the API's own error body, unless the
    status is listed in _allow (per-item lookups where a 404 is itself an answer)."""
    r = requests.get(API_BASE + path, headers=_auth_headers(), params=params, timeout=60)
    if "X-Request-Cost" in r.headers:
        _credits["used"] += int(r.headers["X-Request-Cost"])
    if "X-RateLimit-Remaining" in r.headers:
        _credits["remaining"] = r.headers["X-RateLimit-Remaining"]
    if r.status_code >= 400 and r.status_code not in _allow:
        try:
            body = json.dumps(r.json())
        except ValueError:
            body = r.text[:500]
        sys.exit("HTTP %d from %s: %s" % (r.status_code, path, body))
    return r


def cluster_url(cluster):
    # The free payload carries `slug` (canonical page) and `cluster_id`; the last 8 hex
    # chars of the id also resolve, via a 301 to the slug, when slug is missing.
    ident = cluster.get("slug") or cluster.get("short_id") or cluster.get("cluster_id", "").replace("-", "")[-8:]
    return "%s/cluster/%s" % (SITE, ident)


def report_credits():
    # Stderr, so it never pollutes piped output (brief.md, blocklists, JSON).
    # Keys without a daily cap send no remaining-credits header.
    left = ", remaining today: %s" % _credits["remaining"] if _credits["remaining"] is not None else ""
    sys.stderr.write("[threatcluster] credits used this run: %d%s\n" % (_credits["used"], left))

DEFAULT_KEYWORDS = ["bank", "hospital", "school"]


def matched(keywords, *fields):
    blob = " ".join(str(f or "") for f in fields).lower()
    return ", ".join(k for k in keywords if k.lower() in blob) or "(matched on other fields)"


def main():
    ap = argparse.ArgumentParser(description="Dark-web keyword hits for brands/domains")
    ap.add_argument("keywords", nargs="*", default=DEFAULT_KEYWORDS, help="brand names, domains, subsidiaries")
    ap.add_argument("--per-bucket", type=int, default=25, help="max hits per bucket (free tier caps at 5)")
    args = ap.parse_args()

    data = api_get("/darkweb/keyword-hits", keywords=",".join(args.keywords), per_bucket_limit=args.per_bucket).json()
    hits = data.get("hits", {})
    print("Keywords: %s" % ", ".join(data.get("keywords", args.keywords)))
    days = data.get("lookback_days")
    print("Total hits: %s%s\n" % (data.get("total", 0), " (window: last %s days)" % days if days else ""))

    for v in hits.get("victims", []):
        print("VICTIM   %s  %-14s %-32s %s  %s"
              % ((v.get("discovered") or "")[:10], v.get("group_name") or "?", (v.get("victim_name") or "?")[:32],
                 v.get("country") or "--", v.get("sector") or ""))
        print("         matched: %s  %s/dark-web/victim/%s" % (matched(args.keywords, v.get("victim_name")), SITE, v.get("id", "")))
    for g in hits.get("groups", []):
        print("GROUP    %s  %s/dark-web/group/%s" % (g.get("name") or g.get("group_name") or "?", SITE, g.get("name") or ""))
    empty = [k for k in ("victims", "groups") if not hits.get(k)]
    if empty:
        print("\nNo hits in: %s" % ", ".join(empty))
    report_credits()


if __name__ == "__main__":
    main()
The shell one-liner, brand-domain-monitor.sh:
#!/usr/bin/env bash
# brand-domain-monitor.sh: dark-web keyword hits for the comma-separated keywords in arg 1. 3 credits. Free tier OK.
# usage: ./brand-domain-monitor.sh "acme,acme-corp.example"
set -euo pipefail
: "${THREATCLUSTER_API_KEY:?set THREATCLUSTER_API_KEY (free keys: https://threatcluster.io/about/api)}"
BASE="${THREATCLUSTER_API_BASE:-https://threatcluster.io/api/public/v1}"
SITE="${THREATCLUSTER_SITE:-https://threatcluster.io}"
# A tc_... key goes in X-API-Key; anything else is a bearer (e.g. from `tc login`).
if [[ "$THREATCLUSTER_API_KEY" == tc_* ]]; then AUTH="X-API-Key: $THREATCLUSTER_API_KEY"; else AUTH="Authorization: Bearer $THREATCLUSTER_API_KEY"; fi
# tc_get <path> [curl -G args...]: prints the body; on HTTP >= 400 prints the API error to stderr and fails.
tc_get() { local path=$1; shift; local out code
  out=$(curl -sS -G -H "$AUTH" -w $'\n%{http_code}' "$BASE$path" "$@"); code=${out##*$'\n'}
  if [ "$code" -ge 400 ]; then echo "HTTP $code from $path: ${out%$'\n'*}" >&2; return 1; fi; printf '%s' "${out%$'\n'*}"; }
tc_get /darkweb/keyword-hits --data-urlencode "keywords=${1:?comma-separated keywords}" --data-urlencode per_bucket_limit=25 \
 | jq -r --arg site "$SITE" '"total hits: \(.total)",
     (.hits.victims[]  | "VICTIM  \(.discovered[:10])  \(.group_name)  \(.victim_name)  (\(.country // "--"))  \($site)/dark-web/victim/\(.id)"),
     (.hits.groups[]   | "GROUP   \(.name // .group_name)")'
Output
From a run on 29 September 2026. Yours will differ as the corpus moves.
Keywords: bank, hospital, school
Total hits: 13

VICTIM   2026-09-29  m3rx           iccsi.com                        --  Professional Services
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/9f13930fa0e4eae8
VICTIM   2026-09-29  n0n            Precision Facades Ltd            GB  Manufacturing
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/d0b4b33891a0fcf7
VICTIM   2026-09-28  threeam        stjames.wa.edu.au                AU  Education
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/d595441cb91890bc
VICTIM   2026-09-28  akira          Knit                             --  Technology
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/ffc38f0ed1157bec
VICTIM   2026-09-28  safepay        fedelmundo.com.ph                PH  Other
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/060bd72001aed1df
VICTIM   2026-09-28  incransom      nsbsd.org                        US  Government & Defense
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/cdeba3747de9ffaa
VICTIM   2026-09-27  storm          First Secure Bank Group          US  Financial Services
         matched: bank  https://threatcluster.io/dark-web/victim/6540f7c91c56d6a7
VICTIM   2026-09-26  thegentlemen   ANP Health                       BR  Healthcare
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/08178a531633ff94
VICTIM   2026-09-25  metaencryptor  Platinum Healthcare Staffing     US  Healthcare
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/f2b116f8b7ff0f0c
VICTIM   2026-09-24  rhysida        NEAD Pro                         --  Not Found
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/4f0f4bab598e5c5d
VICTIM   2026-09-23  clop           COLUMBIABANK.COM(UMPQUABANK.COM) US  Financial Services
         matched: bank  https://threatcluster.io/dark-web/victim/73a418dfa92a6708
VICTIM   2026-09-22  kairos         Krapf Group                      US  Manufacturing
         matched: (matched on other fields)  https://threatcluster.io/dark-web/victim/086822b45b7ac36c
VICTIM   2026-09-22  booba project  Tulare Western High School       US  Education
         matched: school  https://threatcluster.io/dark-web/victim/eec5f3f07068bbfe

No hits in: groups
[threatcluster] credits used this run: 3
The file on GitHub: brand-domain-monitor.pyand brand-domain-monitor.sh.
Goes well with
- Sector ransomware watch for Slack: New dark-web ransomware victims for a sector/country, as a Slack message.
- Vendor in the news: Which of my vendors/products are in incident reporting this week?
- A lookup tool for LLM agents: A tool-calling function `threatcluster_lookup(query)` for LLM agents.
- Bash integration: curl and jq in shell scripts and cron
All recipes: /build. Endpoint reference: /api/public/v1/docs.